Error Handling
Every plugin node declares an error output port alongside its success port (and, for some node types, one or more outcome ports). error means one thing only: the node could not do its job — a configuration, parse, or infrastructure failure. A deliberate rejection is not a failure and does not come out here; it leaves on its own outcome port with the response already prepared.
Failures are not exceptions that abort the pipeline — they are routed through the graph like any other output, and the Context travels with them, so error handlers see the full request state.
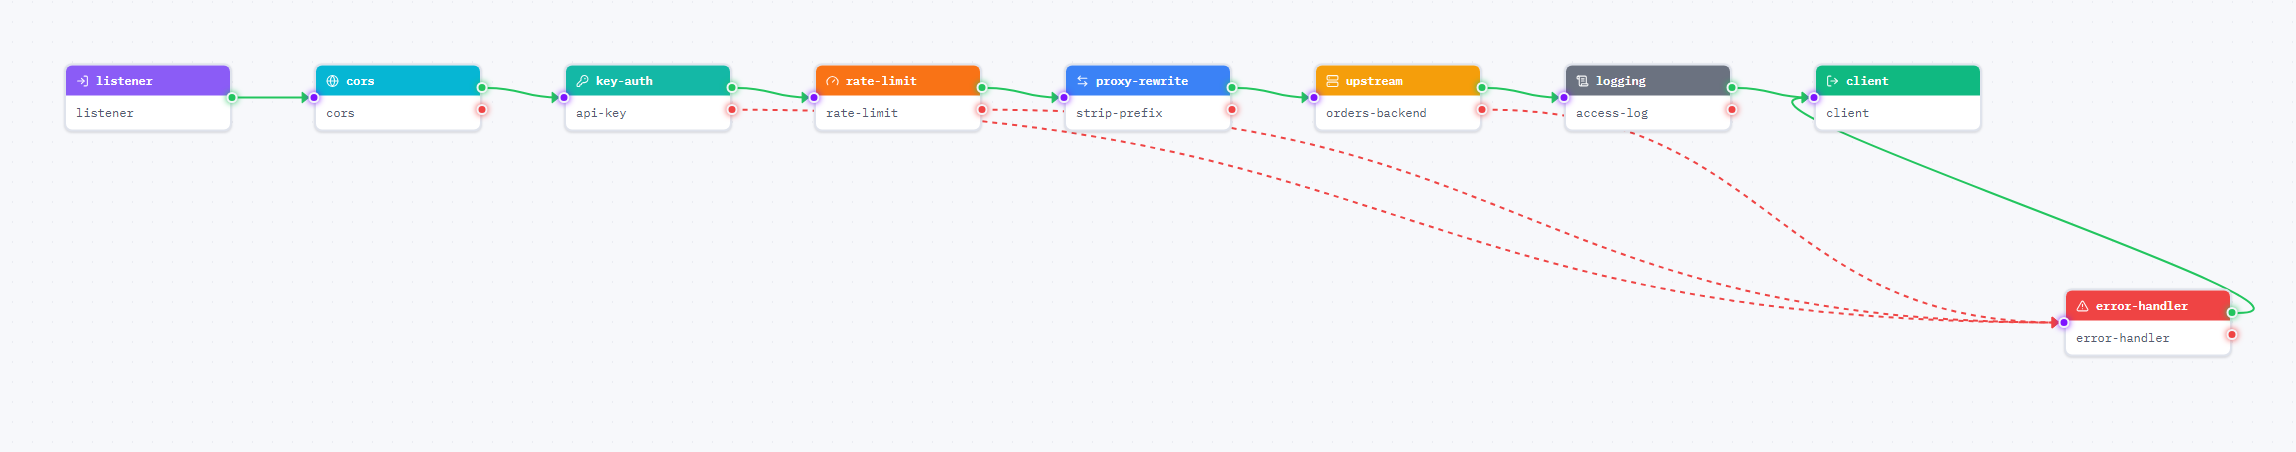
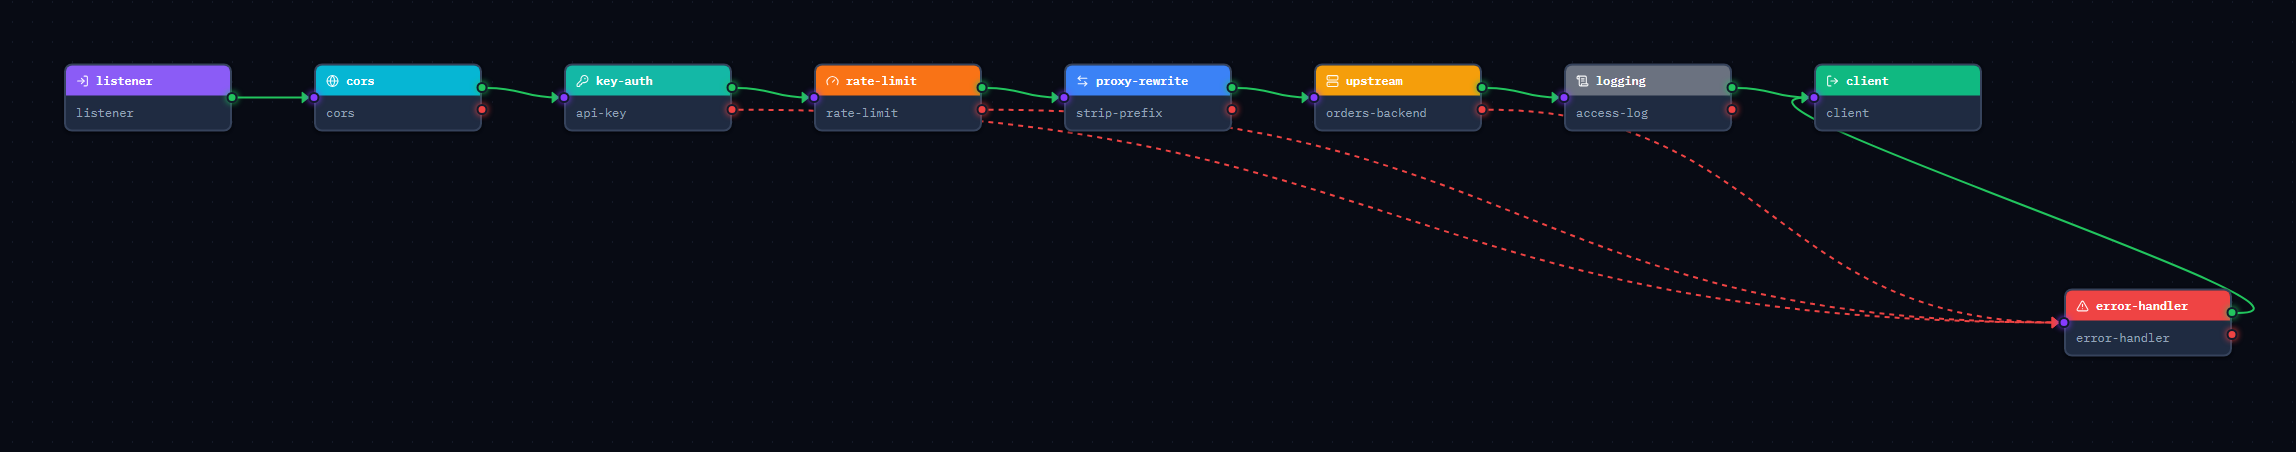
What happens when a node fails
When a plugin returns an error, the engine:
- tags the error with the failing node's
id; - appends it to
context.errors(an append-only list — earlier errors are preserved); - picks the next node in this order:
| Priority | Destination | When |
|---|---|---|
| 1 | Per-node error edge | The failing node's error port is wired (from: backend.error) |
| 2 | Policy catch-all | The policy declares error_handler: <node_id> |
| 3 | Generic 500 | Neither exists — execution stops |
The generic fallback writes status 500 with a JSON body:
{"error": "internal_error", "message": "Unhandled error in routing policy"}
Graph execution itself never fails: every outcome, including the fallback, is expressed through the returned context's response.
Per-node error edges
Wire a specific node's error port to a handler to give that failure mode its own treatment:
edges:
  - from: backend.error
    to: error-handler.in
  - from: error-handler.success
    to: client.in
The error-handler plugin inspects the error and renders a custom response using a template:
- id: error-handler
  type: error-handler
  config:
    status_code: 502
    body_template: '{"error": "{{error.code}}", "message": "{{error.message}}"}'
A context that reaches the handler with no error record — which is what every outcome exit looks like — passes through untouched: same status, same body, same headers. So routing a denied or limited port here is harmless but pointless. Wire outcome ports straight to client, and reshape them with response-rewrite or exit-transformer (always: true) if needed.
Policy-level catch-all
A policy can name one node as its catch-all via the top-level error_handler field:
policies:
  - name: echo-policy
    error_handler: error-handler
Any node whose error port is not wired falls through to this node on failure. This prevents unhandled errors from surfacing as generic 500s. Being named as the catch-all counts as "connected" for validation purposes, so the handler node does not need explicit incoming edges.
Error handlers are regular nodes: they execute like any other node, continue through their own success edge (typically to the client node), and if they themselves fail, the same propagation rules apply to their error.
Validation rules
Every policy is validated before compilation — at startup, on hot-reload, and on Admin API writes — so malformed graphs are rejected with actionable messages instead of failing at request time. The enforced rules:
| Rule | Detail |
|---|---|
| Listener required | The policy must contain a listener node |
| Client required | The policy must contain a client node |
| Edges resolve | Every edge's from and to must reference an existing node |
| Fan-in unrestricted | Any number of edges may converge on the same input port — several paths can deliver the response or route errors to the same node (fan-out and cycles are rejected later, at compile time) |
| No orphans | Every node must have at least one incoming or outgoing edge; being named as the policy-level error_handler counts as connected |
| Catch-all resolves | error_handler, if set, must reference an existing node |
These structural checks collect all violations rather than stopping at the first, and a failed validation on reload leaves the previous configuration serving traffic — see Architecture. The port checks that run afterwards, at compile time (unknown port name, fan-out, mandatory outcome wiring, cycles), report the first violation and stop.